OCR Data Capture & Extraction
Over 100 Five-star Reviews • 20+ Years of Experience • Serving the San Francisco Bay Area, California
Organizations across the San Francisco Bay Area depend on accurate, accessible records to operate, scale, and remain compliant. OCR Data Capture & Intelligent Document Processing is the disciplined practice of converting physical documents into structured, machine-readable data that can be searched, validated, and relied on—not merely stored.
At its foundation is Optical Character Recognition (OCR), which converts scanned images into usable text.
Within professional data capture services, OCR is combined with data extraction, form processing, indexing, and validation to transform unstructured paper files into structured outputs such as searchable PDFs, text, or XML. This enables reliable retrieval, audit readiness, and seamless integration with downstream systems.
Over 20 years, eRecordsUSA has delivered OCR data capture services purpose-built for bulk document projects both automated and manual across the Greater Bay Area, including San Francisco, Oakland, San Jose, and surrounding cities. With proven workflows and local expertise, eRecordsUSA converts paper archives into dependable digital assets and extracted that organizations can trust.
When document volume grows, accuracy and control matter. Partner with a local Bay Area specialist for secure, high-volume OCR data capture and intelligent document processing.

OCR for PDF: Recognize text for a searchable PDF
OCR data capture is used when organizations need accurate, searchable, and structured access to large volumes of records without the inefficiencies and risks of manual data entry. At scale, it supports operational continuity, compliance readiness, and long-term information management.

eRecordsUSA – Trusted Choice for OCR Data Extraction
Making Records Searchable and Accessible
OCR converts scanned documents into searchable, machine-readable files, allowing teams to quickly locate information across large digital archives without relying on paper storage.
Improving Operational Efficiency
By eliminating manual re-entry and paper handling, OCR data capture accelerates workflows, reduces errors, and enables teams to work directly with reliable digital records.
Supporting Audits, Compliance, and Retention
Structured data and consistent indexing make it easier to respond to audits, regulatory reviews, and retention requirements with confidence and accuracy.
Enabling Reporting, Analysis, and Integration
Extracted data can be delivered in structured formats that support analytics, reporting, and integration with document management or business systems.
Our Secure 7-Step Scanning Workflow
How Does OCR Data Capture & Extraction Work for Bulk Document Projects?
OCR data capture and extraction at scale is not a single action—it is a controlled, multi-stage service workflow designed to protect data integrity, maintain accuracy, and support high-volume processing. At eRecordsUSA, every bulk OCR project follows a standardized execution framework that ensures documents move securely and predictably from intake to delivery.
1. Secure Document Intake & Project Setup
2. Document Preparation & Batch Structuring
3. High-Resolution Document Scanning
4. Optical Character Recognition (OCR) Processing
5. Structured Data Extraction & Indexing
7. Output Formatting & File Standardization
6. Quality Assurance & Validation Controls
8. Secure Delivery & Digital Handoff
From Fortune 500 Companies to libraries to the public sector
Industries We Support Across the San Francisco Bay Area
OCR data capture requirements vary widely by industry, especially when documents must meet regulatory, operational, or archival standards. eRecordsUSA supports organizations across multiple sectors with industry-specific OCR data capture and intelligent document processing workflows designed for accuracy, security, and scale.
Audience Segments We Serve
- Healthcare & Life Sciences — Medical records, patient files, lab reports, and compliance documentation are digitized with precise indexing and HIPAA-aligned handling, enabling secure access, audits, and long-term retention.
- Legal & Compliance-Driven Organizations — Law firms, courts, and compliance teams rely on OCR data extraction for contracts, case files, discovery records, and regulatory documents—producing searchable, well-indexed records suitable for review and retention.
- Financial Services & Accounting — Financial records scanning, like Invoices, statements, tax records, and accounting files, is processed to extract structured data that supports reconciliation, reporting, and audit readiness at scale.
- Government, Education & Research — Public records, administrative files, student records, and research documentation are digitized to preserve historical integrity while improving accessibility and retrieval.
All Oversized Documents We Scan & Digitize
What Makes Intelligent Document Processing Different from Basic OCR?
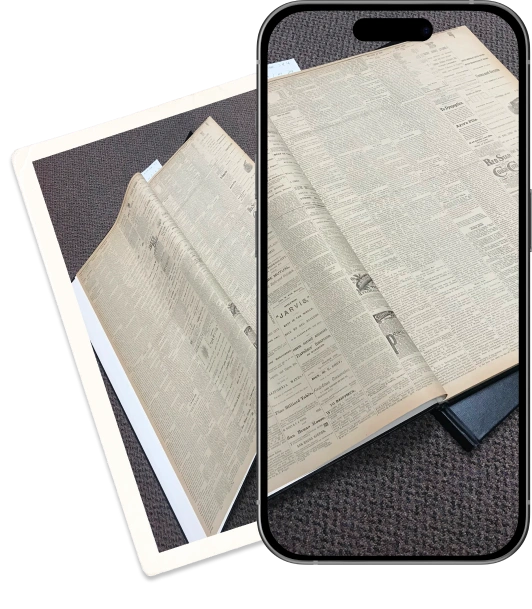
Basic OCR converts scanned images into readable text, but text alone does not meet the needs of organizations handling large volumes of records or regulated data. Intelligent Document Processing (IDP) applies OCR within a controlled service framework that delivers structured, validated, and usable data, not just text output.




Extracting Text from PDF Files Using OCR
Why Choose eRecordsUSA for OCR Data Extraction?
For more than two decades, eRecordsUSA has delivered structured OCR data extraction services for organizations managing high-volume, multi-year document archives. All OCR data extraction is performed in-house at our secure Bay Area facility under documented chain-of-custody procedures. Physical intake, preparation, scanning, OCR processing, data validation, and structured output delivery are executed within a controlled environment. This centralized operational model ensures accountability at every stage, from initial receipt through final digital delivery.
Facility-Based OCR Processing at Our Secure Fremont Lab
- In-house OCR data capture and extraction handled by trained local employees
- Controlled intake, staging, and processing environment for bulk document projects
- High-volume scanning + OCR workflows designed for consistent output quality
- Secure delivery options available (cloud transfer, storage in Google Drive, Dropbox, secure handoff)
Built for High-Volume, Multi-Year, and Mixed Document Sets
- Proven workflows for bulk archives and ongoing high-volume intake
- Supports unstructured-to-structured conversion for varied record types and layouts
- Form processing capability for structured and semi-structured documents
- Output standardization for searchable PDFs, text, CSV, and XML formats
Secure Handling, Chain-of-Custody, and Compliance Controls
- Chain-of-custody tracking from intake through extraction and delivery
- Access-controlled handling to limit exposure to authorized personnel only
- HIPAA-level security practices for sensitive and regulated records
- Retention, return, or certified disposition options based on project requirements
Trusted Credentials and Client-Verified Accountability
- ISO-certified small business with documented operational standards
- Women-owned and minority-owned, locally owned and operated in the Bay Area
- 5-star Google and Yelp ratings with references available upon request
- Free estimates and free consultation for bulk OCR projects across the Greater Bay Area
FAQs About OCR Scanners & Data Extraction
1. How is OCR data extraction priced for bulk document projects?
OCR data extraction pricing depends on document volume, format complexity, data fields required, and validation needs. Bulk projects are typically priced per page or per batch after evaluating accuracy and output requirements.
2. Can OCR data capture integrate with existing document management systems?
Yes. OCR data capture outputs structured, machine-readable files that can integrate with document management systems through standardized formats such as searchable PDF, CSV, or XML.
3. What preparation is required before sending documents for OCR processing?
Minimal preparation is needed. Documents can be bound or loose. Project requirements are defined upfront, and preparation steps such as sorting or indexing are handled as part of the OCR service workflow.
4. Can OCR data extraction support ongoing or recurring document intake?
Yes. OCR data capture services can be structured for recurring or ongoing intake, enabling consistent processing of new records while maintaining uniform formats, indexing, and validation standards.
5. How does OCR data capture support records retention policies?
OCR data capture enables structured indexing and metadata assignment, allowing organizations to apply retention schedules, access controls, and audit-ready storage aligned with internal and regulatory requirements.
6. Is OCR data extraction suitable for legacy or poor-quality documents?
Yes. OCR workflows include image enhancement, exception handling, and validation steps to improve recognition accuracy for older, damaged, or low-quality documents commonly found in legacy archives.
7. What happens to original documents after OCR data capture?
Original documents can be securely returned, retained for a defined period, or certified for secure destruction, depending on project requirements and organizational policies.
8. How long does a bulk OCR data capture project typically take?
Project timelines depend on document volume, complexity, and output requirements. Bulk OCR projects are scheduled using throughput planning to ensure predictable turnaround without compromising accuracy.
Certified scanning, purpose-built for wide-format records
20+ Years of Trusted Experience in OCR Data Capture & Intelligent Document Processing
At eRecordsUSA, OCR data capture is treated as a mission-critical service, not a background task.
For more than two decades, we have helped organizations transform high-volume paper records into structured, machine-readable data that supports operational efficiency, regulatory compliance, and long-term information access. Our experience spans complex document environments where accuracy, consistency, and accountability are non-negotiable.
All OCR data extraction work is performed in-house at our secure Fremont, California facility, allowing us to maintain full chain-of-custody control from intake through delivery. Every project follows disciplined workflows designed specifically for bulk document processing, ensuring records are scanned, recognized, extracted, and validated under controlled conditions.
This service-led approach eliminates the risks associated with fragmented or software-only OCR solutions and delivers dependable, business-ready data.
eRecordsUSA processes large volumes of paper records, multi-year archives, and mixed-format document collections that require reliable OCR and data extraction.
Unstructured documents are converted into searchable PDFs and structured digital formats, with indexing and metadata applied to support retrieval, audits, and system integration. Our workflows accommodate forms, financial records, healthcare documentation, compliance files, and operational records without compromising accuracy or consistency.
Our OCR data capture services are supported by HIPAA-aligned security practices, documented chain-of-custody tracking, and controlled access environments. Metadata structures are aligned with organizational and retention requirements, and all files are delivered through secure transfer methods, approved cloud delivery, or encrypted storage options. This ensures data remains protected, traceable, and usable long after project completion.
Whether digitizing operational records, regulated documents, or large archival collections, eRecordsUSA delivers scalable, preservation-grade OCR data capture and extraction—trusted by institutions, executed locally, and built to support long-term data reliability.
Top Scanning & Conversion Services
⭐ What Our Clients Are Saying: Real Results, Real Reliability
Rated 5 Starts For Our Document and Book Scanning Services
At eRecordsUSA, clients across libraries, museums, archives, academic institutions, and government agencies trust us with their most fragile and valuable collections. We don’t just scan—we preserve history. From non-contact scanning to metadata-rich indexing, we deliver digital archives that are as accurate as they are accessible.


Want to See How We Compare? Let us quote your next digitization project and show you why we’re trusted by leading institutions nationwide.